> ## Documentation Index
> Fetch the complete documentation index at: https://docs.fiddler.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# LiteLLM Integration
> Integrate LiteLLM with Fiddler for unified LLM cost tracking, latency monitoring, and LLM call observability — via the LiteLLM SDK or the LiteLLM proxy gateway.
## Overview
[LiteLLM](https://docs.litellm.ai/) provides a unified interface for calling 100+ LLM providers.
This page covers **observability**: routing LiteLLM's OpenTelemetry traces to Fiddler.
Pick your path before you start:
| Goal | Recommended path |
| - | - |
| Trace prompts, responses, tokens, costs, and latency | This page |
| Block or redact PII and secrets inline | [LiteLLM Guardrails](/protection/litellm-guardrails) |
| Observe and protect the same traffic | Configure both — they are independent and share no settings |
Fiddler supports two integration modes:
| Mode | Best for | Required packages |
| - | - | - |
| **LiteLLM SDK** | Applications calling LLM providers directly via `litellm.completion()` | `litellm`, `opentelemetry-sdk`, `opentelemetry-exporter-otlp-proto-http` |
| **LiteLLM Proxy** | Teams routing all LLM traffic through a centrally managed LiteLLM proxy gateway | `litellm[proxy]`, `opentelemetry-sdk`, `opentelemetry-exporter-otlp-proto-http` |
No Fiddler-specific package is required in either mode,
but the OpenTelemetry SDK and OTLP/HTTP exporter packages are —
neither `litellm` nor `litellm[proxy]` installs them
(verified at LiteLLM 1.96.2; they ship only in LiteLLM's Docker images).
If they are missing, requests keep succeeding and **traces silently never appear** —
see [Troubleshooting Trace Delivery](#troubleshooting-trace-delivery).
Both modes work by routing OpenTelemetry traces to Fiddler's OTLP ingestion endpoint
using standard environment variables.
This page was verified end-to-end with LiteLLM 1.96.2;
use **LiteLLM 1.85.0 or later** —
earlier versions have known trace-content gaps
(see [Known LiteLLM Upstream Caveats](#known-litellm-upstream-caveats)),
and versions before 1.81.0 do not emit the `gen_ai.operation.name` attribute
Fiddler uses to classify spans.
If the same proxy also runs [Fiddler guardrails](/protection/litellm-guardrails),
that page's higher floor (1.91.0) governs the combined deployment.
***
## LiteLLM SDK Integration
### Overview
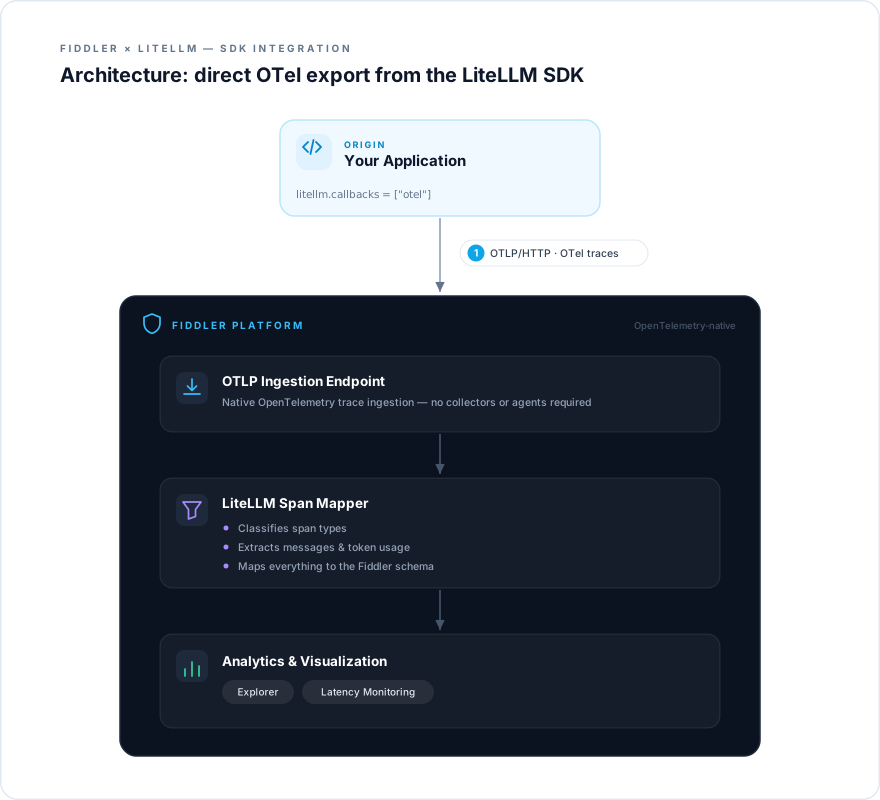
LiteLLM includes a built-in OpenTelemetry integration.
When you enable it and point the OTLP exporter at Fiddler,
every LLM call is automatically traced.
Fiddler natively ingests LiteLLM-generated OTel traces and maps them to the Fiddler schema,
giving you observability over prompts, responses, token usage, and cost
across all LLM providers.
The following SDK functions are supported:
| SDK Function | `gen_ai.operation.name` | Fiddler Span Type |
| - | - | - |
| `litellm.completion()` / `litellm.acompletion()` | `chat` / `completion` / `acompletion` | `llm` |
| `litellm.text_completion()` / `litellm.atext_completion()` | `text_completion` / `atext_completion` | `llm` |
| `litellm.responses()` / `litellm.aresponses()` | `responses` / `aresponses` | `llm` |
| `litellm.anthropic_interface.messages.create()` / `acreate()` | `anthropic_messages` | `llm` |
| `litellm.generate_content()` / `litellm.agenerate_content()` | `generate_content` / `agenerate_content` | `llm` |
| `litellm.embedding()` / `litellm.aembedding()` | `embedding` / `aembedding` | `embedding` |
| `litellm.rerank()` / `litellm.arerank()` | `rerank` / `arerank` | `reranker` |
| `litellm.image_generation()`, `litellm.speech()`, `litellm.transcription()`, `litellm.moderation()`, `litellm.ocr()` (and async variants) | operation-specific | `unknown` |
Fiddler's LLM observability focuses on text-based generative completions:
image, audio, moderation, and OCR operations are ingested and remain visible in traces,
but carry the `unknown` span type rather than `llm`.
### Architecture
 ### Prerequisites
* A Fiddler account with a GenAI application already created,
and the application's UUID
(open the application in the Fiddler UI and copy the UUID from the URL or application settings)
* A Fiddler API key, created under **Settings → [Credentials](/reference/administration/settings#credentials)**
* LiteLLM **1.85.0 or later** plus the OpenTelemetry packages:
```bash theme={null}
uv add litellm opentelemetry-sdk opentelemetry-exporter-otlp-proto-http
```
* A valid LLM provider API key (e.g. `OPENAI_API_KEY` for OpenAI models)
### Quick Start
#### Step 1: Set Environment Variables
Set these before starting your application:
```bash theme={null}
# Fiddler OTel ingestion
export OTEL_EXPORTER_OTLP_ENDPOINT="https://your-fiddler-instance.com"
export OTEL_EXPORTER_OTLP_HEADERS="authorization=Bearer ,fiddler-application-id="
export OTEL_RESOURCE_ATTRIBUTES="application.id="
# LLM provider key (name varies by provider)
export OPENAI_API_KEY="your-openai-key"
```
Three details that prevent silent failures:
* **The endpoint is your instance base URL.**
LiteLLM appends `/v1/traces` automatically —
the final request is `POST https://your-fiddler-instance.com/v1/traces`
over OTLP/HTTP (the default protocol once an endpoint is set; standard HTTPS port).
* **Header values are parsed literally.**
LiteLLM splits `OTEL_EXPORTER_OTLP_HEADERS` on commas and the first `=` of each part,
with no URL-decoding and no whitespace trimming:
keep the literal space in `Bearer `, never URL-encode it,
and put no space after the comma.
* **The application UUID appears in two places, doing different jobs.**
The `fiddler-application-id` header authenticates the request;
the `application.id` resource attribute routes spans to your application.
Both are required and must match.
#### Step 2: Enable the Built-In OTel Callback
Add one line to your application startup:
```python theme={null}
import litellm
litellm.callbacks = ["otel"]
```
#### Step 3: Make Completions as Normal
No other code changes are required:
```python theme={null}
response = litellm.completion(
model="gpt-4o-mini",
messages=[
{"role": "system", "content": "You are a helpful assistant."},
{"role": "user", "content": "What is the capital of France?"},
],
)
print(response.choices[0].message.content)
```
Every call is now automatically traced and exported to Fiddler.
#### Step 4: Verify Traces Are Arriving
Open the Fiddler UI and navigate to your application's **Explorer**.
You should see the trace within a few seconds of making your first completion call.
If nothing appears, work through [Troubleshooting Trace Delivery](#troubleshooting-trace-delivery).
### What Gets Captured
**Message Content**
| Fiddler Field | Source |
| - | - |
| System prompt | First `role: system` message |
| User input | Last `role: user` message (the most recent user turn) |
| Assistant output | Last `role: assistant` message |
**Token Usage**
| Attribute | Description |
| - | - |
| `gen_ai.usage.input_tokens` | Prompt tokens consumed |
| `gen_ai.usage.output_tokens` | Completion tokens generated |
| `gen_ai.usage.total_tokens` | Total tokens |
**Model Information**
`gen_ai.system` and `gen_ai.request.model` are stored at their unprefixed keys,
making them queryable via `SpanAttribute::gen_ai.system` and `SpanAttribute::gen_ai.request.model`.
| Attribute | Description |
| - | - |
| `gen_ai.request.model` | Model requested (e.g. `gpt-4o-mini`) |
| `gen_ai.response.model` | Model actually used |
| `gen_ai.system` | Provider (e.g. `openai`, `anthropic`) |
**Cost Metadata**
LiteLLM emits `gen_ai.cost.input_cost`, `gen_ai.cost.output_cost`, and `gen_ai.cost.total_cost`
whenever it can price the model from its cost map;
models LiteLLM cannot price emit no cost attributes.
Fiddler stores these attributes verbatim and resolves them to its cost concepts at query time.
**Conversation Grouping**
Fiddler groups spans into conversations via `gen_ai.conversation.id`.
By default each request is its own conversation (the OTel trace ID is used);
to group a multi-turn conversation, send an `x-genai-conversation-id` header
with the same value on every request of the conversation (proxy mode).
### Supported Features
| Feature | Support | Notes |
| - | - | - |
| Chat/text completion tracing | ✅ Full | Prompts, responses, token usage via `completion()`, `text_completion()` |
| Responses API tracing | ✅ On LiteLLM ≥ 1.85.0 | Input/output messages and instructions missing on earlier versions — see [Known LiteLLM Upstream Caveats](#known-litellm-upstream-caveats) |
| Anthropic Messages API tracing | ✅ On current LiteLLM | The `system` prompt is coalesced into `gen_ai.system_instructions` on current versions |
| Token usage | ✅ Full | Input, output, and total tokens |
| Model information | ✅ Full | Requested and actual model |
| Cost tracking | ✅ When priced | Emitted whenever LiteLLM's cost map covers the model |
| Embeddings, rerank | ✅ As `embedding` / `reranker` span types | Captured with token and cost metadata |
| Images, audio, moderation, OCR | ⚠️ As `unknown` span type | Visible in traces, not classified as `llm` |
| Conversation grouping | ⚠️ Header-driven | Requires `x-genai-conversation-id`; otherwise one conversation per request |
***
## LiteLLM Proxy Integration
### Overview
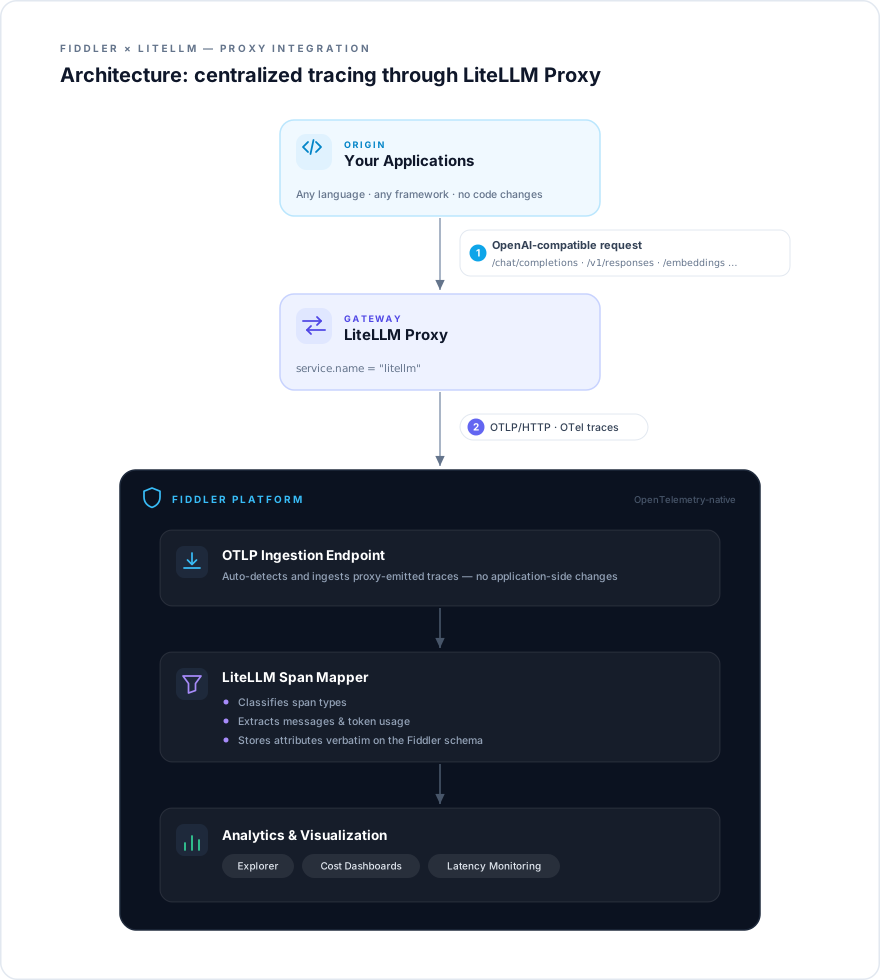
The LiteLLM proxy is an OpenAI-compatible gateway that lets you call 100+ LLM providers
through a single API.
When the proxy emits OpenTelemetry traces, Fiddler automatically detects and ingests them —
no application-side changes required.
This gives you observability over every LLM call routed through your proxy:
prompts, responses, token usage, cost metadata, and latency —
across all models and providers in one place.
### Architecture
 ### When to Use This Integration
Use the LiteLLM proxy integration when:
* You are already running LiteLLM proxy as your LLM gateway
* You want to monitor all LLM traffic centrally regardless of underlying provider (OpenAI, Anthropic, Bedrock, etc.)
* You want cost attribution and latency tracking without instrumenting individual applications
### Prerequisites
* A Fiddler GenAI application and its UUID, plus a Fiddler API key
(**Settings → [Credentials](/reference/administration/settings#credentials)**)
* LiteLLM proxy **1.85.0 or later** with the OpenTelemetry packages:
```bash theme={null}
uv add "litellm[proxy]" "fastapi<0.140.7" opentelemetry-sdk opentelemetry-exporter-otlp-proto-http
```
The `"fastapi<0.140.7"` pin works around a LiteLLM 1.96.x dependency conflict
that otherwise breaks proxy startup
(`ImportError: cannot import name 'get_flat_dependant'`);
remove it once upstream ships a fix.
* A `config.yaml` with at least one configured model (`model_list`) and a provider API key
* Network access from the proxy host to your Fiddler instance over HTTPS
### Quick Start
#### Step 1: Configure the Proxy to Emit OpenTelemetry
Enable the OTel callback in `config.yaml` and set the export target in the environment:
```yaml theme={null}
model_list:
- model_name: gpt-4o-mini
litellm_params:
model: openai/gpt-4o-mini
api_key: os.environ/OPENAI_API_KEY
litellm_settings:
callbacks: ["otel"]
```
```bash theme={null}
export OPENAI_API_KEY=""
export OTEL_EXPORTER_OTLP_ENDPOINT="https://your-fiddler-instance.com"
export OTEL_EXPORTER_OTLP_HEADERS="authorization=Bearer ,fiddler-application-id="
export OTEL_RESOURCE_ATTRIBUTES="application.id="
litellm --config config.yaml
```
The endpoint is your instance base URL — LiteLLM appends `/v1/traces` automatically
and exports over OTLP/HTTP.
The same header-format and two-locations rules from the
[SDK integration](#litellm-sdk-integration) quick start apply verbatim.
#### Step 2: Verify Traces Are Arriving
Make a test request through your proxy:
```bash theme={null}
curl -X POST http://localhost:4000/v1/chat/completions \
-H "Content-Type: application/json" \
-d '{
"model": "gpt-4o-mini",
"messages": [{"role": "user", "content": "Hello"}]
}'
```
Then open the Fiddler UI and navigate to your application's **Explorer**.
You should see the trace within a few seconds.
If not, see [Troubleshooting Trace Delivery](#troubleshooting-trace-delivery).
### Using with OpenAI Codex CLI
[OpenAI Codex CLI](https://github.com/openai/codex) does not need its own Fiddler integration.
Codex's native OpenTelemetry **traces** carry only token counts —
no prompt, response, or tool content.
(That content exists only in Codex's OpenTelemetry **logs**, which Fiddler does not ingest.)
So the recommended way to observe Codex in Fiddler is to point it at your LiteLLM proxy.
The proxy then emits full `llm` spans (prompt + response + token usage)
that Fiddler ingests through the integration described above, with no Fiddler-side code.
#### Step 1: Use LiteLLM 1.85+ With a Codex-Compatible Model
Codex uses the OpenAI Responses API,
whose content is fully captured in LiteLLM's OTel traces from **1.85.0** onward:
```bash theme={null}
uv add "litellm[proxy]>=1.85.0" "fastapi<0.140.7" opentelemetry-sdk opentelemetry-exporter-otlp-proto-http
```
In your proxy `config.yaml`, map an alias (the name Codex will request) to a Codex-capable model.
Use a current Codex-family model from your OpenAI account for the upstream `model` —
for example `gpt-5.2-codex`.
General chat models such as `gpt-4o-mini` will **not** work,
because they reject Codex's tool calls.
```yaml theme={null}
model_list:
- model_name: codex-model # alias Codex requests (any name; reused in Step 2)
litellm_params:
model: openai/ # e.g. gpt-5.2-codex — must accept Codex's tool calls
api_key: os.environ/OPENAI_API_KEY
litellm_settings:
callbacks: ["otel"]
drop_params: true
```
#### Step 2: Point Codex at the Proxy
Add a custom model provider to `~/.codex/config.toml`
so Codex sends requests to your LiteLLM proxy instead of OpenAI directly:
```toml theme={null}
model = "codex-model" # must match the model_name alias from Step 1
model_provider = "fiddler-gw"
[model_providers.fiddler-gw]
name = "Fiddler GW"
base_url = "http://localhost:4000/v1" # your LiteLLM proxy URL
wire_api = "responses" # Codex only supports the Responses API
env_key = "GW_KEY" # any non-empty value; LiteLLM holds the real provider key
```
```bash theme={null}
export GW_KEY=any-non-empty-value
```
#### Step 3: Use Codex Normally
```bash theme={null}
codex exec "Plan a 4-day trip to Japan"
```
Each turn appears in your application's **Explorer** as an `llm` span
with the full user prompt, assistant response, and token usage.
**Requirements and limitations**
* **API-key mode only.** Routing through a proxy uses your OpenAI API key; it does not work with ChatGPT-subscription login.
* **The upstream model must accept Codex's tool calls.** Use a current Codex-family model from your OpenAI account (for example `gpt-5.2-codex`); general chat models such as `gpt-4o-mini` reject Codex's tool format.
### What Gets Captured
#### Span Types
Fiddler classifies LiteLLM spans by the `gen_ai.operation.name` attribute
(and by span name for guardrail spans):
| Traffic | `gen_ai.operation.name` | Fiddler Span Type |
| - | - | - |
| `/chat/completions`, `/completions` | `chat` / `completion` / `acompletion` / `text_completion` / `atext_completion` | `llm` |
| `/v1/responses`, `/responses` | `responses` / `aresponses` | `llm` |
| `/v1/messages` (Anthropic format) | `anthropic_messages` | `llm` |
| Google Gemini native endpoints | `generate_content` / `agenerate_content` (+ streaming variants) | `llm` |
| `/embeddings` | `embedding` / `aembedding` | `embedding` |
| `/rerank` | `rerank` / `arerank` | `reranker` |
| MCP tool invocations | tool-call operations | `tool` |
| LiteLLM guardrail executions | span name `guardrail` | `guardrail` |
| Images, audio, moderation, OCR | operation-specific | `unknown` |
| Internal infrastructure (`self`, `router`, `proxy_pre_call`) | — | `unknown` |
Each proxy request typically produces up to three spans:
`Received Proxy Server Request` (top-level server span),
`litellm_request` (the primary span carrying all attributes),
and `raw_gen_ai_request` (a child span with the raw provider-level request and response).
#### Captured Attributes
**Message Content** —
LiteLLM writes full conversation history as JSON on the span
(`gen_ai.input.messages` / `gen_ai.output.messages`).
Fiddler extracts the first `role: system` message as the system prompt,
the last `role: user` message as the user input,
and the last `role: assistant` message as the assistant output.
If you have disabled message logging in LiteLLM (`turn_off_message_logging: true`),
the message content fields are absent from traces;
token counts and cost metadata are still captured.
**Token Usage** —
`gen_ai.usage.input_tokens`, `gen_ai.usage.output_tokens`, `gen_ai.usage.total_tokens`.
**Model Information** —
`gen_ai.request.model` (requested), `gen_ai.response.model` (actually used),
`gen_ai.system` (provider), queryable via `SpanAttribute::` as on the SDK path.
**Cost Metadata** —
`gen_ai.cost.input_cost`, `gen_ai.cost.output_cost`, `gen_ai.cost.total_cost`,
emitted when LiteLLM can price the model.
Fiddler stores customer attribute keys verbatim —
there is no renaming into Fiddler-specific namespaces —
and resolves cost concepts at query time.
**Proxy Metadata** —
LiteLLM proxy emits `metadata.*` attributes containing API key, team, user,
and routing information, all preserved verbatim for auditing and cost attribution.
**Conversation Grouping** —
as on the SDK path:
send `x-genai-conversation-id` with a stable value per conversation to group multi-turn sessions;
without it, each request is its own conversation.
#### LiteLLM OTel v2
The span and attribute names above describe LiteLLM's default (v1) OpenTelemetry integration.
Setting `LITELLM_OTEL_V2=true` switches the proxy to LiteLLM's semconv-aligned v2 output,
which renames some spans and attributes:
the guardrail span becomes `execute_guardrail `, MCP tool calls become `execute_tool`,
and cost, guardrail, team, and metadata attributes move to the
`litellm.cost.*`, `litellm.guardrail.*`, `litellm.team.*`, and `litellm.metadata.*` namespaces.
Fiddler's span mapper ingests both generations automatically —
traces arrive either way; query the namespace that matches the generation your proxy emits.
***
## Troubleshooting Trace Delivery
Two different failure classes exist, and they look different from your side:
**authentication problems are loud** (the exporter logs an error in *your* logs),
while **routing problems are silent** (the endpoint accepts the spans and they never appear).
Work through the checks in order — they apply to both the SDK and proxy paths.
**1. Did the OTel callback load?**
If the OpenTelemetry packages are missing, requests still succeed and nothing is exported.
The only symptom is a log line at startup (proxy) or on the first request (SDK):
```text theme={null}
Error initializing custom logger: No module named 'opentelemetry'
```
Install `opentelemetry-sdk` and `opentelemetry-exporter-otlp-proto-http` and restart.
**2. Is the exporter pointed at the right place?**
With `OTEL_EXPORTER_OTLP_ENDPOINT` set to your instance base URL,
LiteLLM exports over OTLP/HTTP to `/v1/traces`.
An export failure appears in your logs as:
```text theme={null}
Failed to export span batch code: , reason:
```
A `404` usually means a wrong base URL.
A `401`, `403`, or `404` from a correct URL means the **authentication headers** were rejected —
an invalid API key, an application UUID that does not exist,
or a key without permission on that application.
These header problems are always visible as export errors; they are never silent.
**3. Is the header string formatted exactly right?**
`OTEL_EXPORTER_OTLP_HEADERS` is parsed literally:
comma-separated `key=value` pairs, split on the first `=`,
with no URL-decoding and no whitespace trimming.
Keep the literal space in `Bearer `, never URL-encode it
(a `%20` reaches the server encoded and breaks authentication),
and put no space after the comma.
**4. Do both application-ID locations agree?**
The `fiddler-application-id` **header** authenticates;
the `application.id` **resource attribute** (in `OTEL_RESOURCE_ATTRIBUTES`) routes.
If the resource attribute is missing or carries a different UUID,
the endpoint returns success and the spans are dropped or routed elsewhere —
**this is the silent case**, and there is currently no customer-visible server-side
diagnostic for it.
Verify both values are the same UUID, character for character.
**5. Does the application UUID exist?**
Open the application in the Fiddler UI and copy the UUID from the URL or application settings —
do not construct it by hand.
**6. Send a test span and watch your own logs.**
Make one request, wait a few seconds for the batch exporter to flush,
and confirm no `Failed to export` lines appear.
**7. Check Explorer.**
The trace should appear in the expected application within a few seconds.
Two timing caveats: the batch exporter flushes on an interval (allow \~10 seconds),
and a freshly deployed Fiddler instance may drop spans for the first few minutes
while its pipeline warms up.
If all seven checks pass and traces still do not appear,
contact Fiddler support with the application UUID, the OTel trace ID of a test request,
and the request timestamp — never include prompts, responses, or credentials.
**Message content missing from traces?**
LiteLLM's message logging may be disabled — remove `turn_off_message_logging: true`
from `litellm_settings` to re-enable message capture
(token counts and cost are unaffected by this setting).
**Overrode `OTEL_SERVICE_NAME`?**
Fiddler recognizes LiteLLM spans primarily by their instrumentation scope,
with `service.name` values `litellm` and `litellm-proxy` both recognized as fallbacks.
Leave `OTEL_SERVICE_NAME` unset, or set it to one of those two values.
***
## Known LiteLLM Upstream Caveats
Earlier LiteLLM versions had gaps in the OTel callback that affected every downstream
OTel consumer, not just Fiddler.
Status as of LiteLLM 1.96.2:
**Fixed in LiteLLM 1.85.0 — Responses API content.**
Before 1.85.0, `/v1/responses` traces were missing `gen_ai.input.messages`,
`gen_ai.output.messages`, and the `instructions` system prompt
([BerriAI/litellm#25840](https://github.com/BerriAI/litellm/issues/25840), closed as completed).
Current versions also coalesce the per-endpoint system-prompt field names
(`instructions`, `system`, `system_instructions`) into `gen_ai.system_instructions`.
If you run an older proxy and see token counts but no message content on Responses-API
traffic, upgrade to ≥ 1.85.0.
**Still open — provider attribution on non-chat endpoints.**
For endpoint families other than `/chat/completions`,
LiteLLM may emit an empty `gen_ai.system`
and prefix raw provider attributes on the `raw_gen_ai_request` child span with `llm.None.*`
([BerriAI/litellm#25240](https://github.com/BerriAI/litellm/issues/25240),
closed by the stale-bot without a fix;
the proposed fix [PR #25309](https://github.com/BerriAI/litellm/pull/25309) remains open).
Fiddler's span classification is unaffected —
it keys off `gen_ai.operation.name`, not the provider attribution.
***
## Guardrails
Fiddler also implements the LiteLLM Generic Guardrail API spec,
letting you plug Fiddler's real-time guardrails directly into the LiteLLM proxy gateway.
Once configured, every request routed through the proxy is checked for
**secrets and PII** — blocking or redacting them before the request reaches the model.
Guardrails and observability are configured independently and compose freely
on the same proxy:
the `guardrails` and `litellm_settings.callbacks` keys coexist in one `config.yaml`,
and traces capture the sanitized request —
content redacted by a `pre_call` guardrail never appears in the exported spans.
With the OTel callback enabled on the same proxy,
each guardrail execution is also traced as its own span next to the model call,
so every block or redact decision — and its reason — shows up in Explorer as an audit trail.
See [LiteLLM Guardrails](/protection/litellm-guardrails) for the verified quick start,
check behavior, failure controls, and the full API reference.
***
## Next Steps
* [LiteLLM Guardrails](/protection/litellm-guardrails) — block or redact PII and secrets inline on the same proxy
* [OpenTelemetry Integration](/integrations/agentic-ai/opentelemetry-integration) — instrument custom frameworks by hand when you outgrow built-in callbacks
* [Strands Agents SDK](/integrations/agentic-ai/strands-sdk) — native monitoring if your agents run on Strands
* [LangGraph SDK](/integrations/agentic-ai/langgraph-sdk) — auto-instrumentation for LangGraph applications
* [LiteLLM OTel documentation](https://docs.litellm.ai/docs/proxy/logging#opentelemetry) — LiteLLM's own OpenTelemetry configuration reference